#720 by GitHub stars

cclank/news-aggregator-skill
Comprehensive news aggregator that fetches, filters, and deeply analyzes real-time content from 44+ sources including Hacker News, Lobsters, Dev.to, GitHub, arXiv, Hugging Face Papers, AIHOT, TLDR AI, Import AI, BBC, The Guardian, Al Jazeera, France 24, Reuters fallback, AI Newsletters, WallStreetCN
History
Review weekly changes to SKILL.md before updating. Dates mark the weeks in which we observed each version; checks apply to the recorded commits.
View weekly changes
SKILL.md
Week of Nov 2, 2026 · +0 / −0 lines
Before Network or broad shell → After Network or broad shell
b639b622a79e → b639b622a79e
Diff text is unavailable under the recorded licenses. Line counts and the GitHub link remain available.
Week of Oct 26, 2026 · Line counts unavailable
Before Not checked yet → After Network or broad shell
First observation → b639b622a79e
No earlier version was observed for comparison.
Heat
0.4- Star growth, last 7 daysAhead of 6% of tracked repositories
- Star growth, last 24 hoursAhead of 3% of tracked repositories
- Rank movement, last 7 daysAhead of 5% of tracked repositories
- Commits, last 30 daysAhead of 0% of tracked repositories
- Accounts asking about it through MCP, last 7 daysNot available
- Hot votes this weekAhead of 0% of tracked repositories
Heat never changes the order by stars, and sponsorship never touches it. How heat works
Stars over time
Individual skills in this repository
How it works
news-aggregator-skill
When your agent uses it
Comprehensive news aggregator that fetches, filters, and deeply analyzes real-time content from 44+ sources including Hacker News, Lobsters, Dev.to, GitHub, arXiv, Hugging Face Papers, AIHOT, TLDR AI, Import AI, BBC, The Guardian, Al Jazeera, France 24, Reuters fallback, AI Newsletters, WallStreetCN, Weibo, 少数派, InfoQ 中文, Podcasts, and user-defined OPML feeds. Use when user requests 'daily scans', 'tech news', 'finance updates', 'AI briefings', 'international news', 'deep analysis', or says '如意如意' to open the interactive menu.
What it loads into context
Frontmatter
152 tokensAlways available to the agent
SKILL.md
2,637 tokensWhen the skill is activated
Reference documents
9,170 tokensLoaded on request
Token counts are estimates. Scripts run separately; they are not counted as reference context.
The playbook
- 🔄 Universal Workflow (3 Steps)
- 📰 Unified Report Template
- 🛠<U+FE0F> Tools
- ⚠<U+FE0F> Rules (Strict)
- 📋 Interactive Menu
- Requirements
Scripts executed separately
scripts/daily_briefing.pyscripts/debug_hf_detail.pyscripts/fetch_bensbites.pyscripts/fetch_generic_playwright.pyscripts/fetch_hf_papers_playwright.pyscripts/fetch_news.pyscripts/fetch_user_feeds.pyscripts/process_general_json.pyscripts/rss_parser.pyscripts/test_all_sources.py
Files
.agent/workflows/daily_briefing.mddoc715 bytes.gitignoreasset720 bytesMISTAKES.mddoc6,319 bytesREADME.mddoc7,076 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesSKILL.mdcore9,105 bytesimplementation_plan.mddoc1,824 bytesinstructions/briefing_ai_daily.mddoc1,633 bytesinstructions/briefing_finance.mddoc2,109 bytesinstructions/briefing_general.mddoc3,092 bytesinstructions/briefing_github.mddoc1,165 bytesinstructions/briefing_social.mddoc1,554 bytesinstructions/briefing_tech.mddoc1,491 bytesrequirements.txtdoc24 bytesscripts/daily_briefing.pyruns7,988 bytesscripts/debug_hf_detail.pyruns1,962 bytesscripts/fetch_bensbites.pyruns4,540 bytesscripts/fetch_generic_playwright.pyruns2,613 bytesscripts/fetch_hf_papers_playwright.pyruns4,224 bytesscripts/fetch_news.pyruns41,833 bytesscripts/fetch_user_feeds.pyruns3,473 bytesscripts/process_general_json.pyruns1,960 bytesscripts/rss_parser.pyruns4,255 bytesscripts/test_all_sources.pyruns4,590 bytestemplates.mddoc5,129 bytesuser_sources.opml.exampleasset2,147 bytes
No excerpt is shown for this license. Read the source on GitHub.
View the complete source on GitHubSkills included
- news-aggregator-skill
Repository facts
- License
- No license detected
- Created
- Jan 19, 2026
- Last pushed
- May 27, 2026
- Forks
- 124
- Open issues
- 1
- Project activity
- Slowing
Rank over the last 12 weeks
Now #720 · best #492 · down 111 in 30 days
- #702 on Nov 1
- #704 on Nov 2
- #709 on Nov 3
- #713 on Nov 4
- #716 from Nov 5 to Nov 6
- #720 since Nov 7
54 earlier periods
- #475 on Aug 2
- #500 on Aug 6
- #502 on Aug 10
- #499 on Aug 11
- #497 on Aug 12
- #501 on Aug 14
- #492 on Aug 16
- #511 on Aug 18
- #506 on Aug 20
- #507 on Aug 21
- #511 on Aug 23
- #517 on Aug 25
- #510 on Aug 26
- #521 on Aug 27
- #507 on Aug 29
- #499 on Aug 30
- #525 on Aug 31
- #527 on Sep 1
- #513 on Sep 4
- #508 on Sep 5
- #522 on Sep 6
- #523 on Sep 7
- #535 on Sep 10
- #526 on Sep 13
- #536 on Sep 15
- #548 on Sep 16
- #533 on Sep 19
- #547 on Sep 20
- #561 on Sep 22
- #559 on Sep 23
- #542 on Sep 25
- #562 on Sep 27
- #567 on Sep 28
- #578 on Sep 30
- #553 on Oct 3
- #560 on Oct 4
- #569 on Oct 5
- #585 on Oct 7
- #609 on Oct 8
- #582 on Oct 11
- #596 on Oct 12
- #609 on Oct 15
- #617 on Oct 16
- #596 on Oct 18
- #624 on Oct 19
- #630 on Oct 20
- #635 on Oct 21
- #621 on Oct 22
- #606 on Oct 24
- #681 on Oct 25
- #691 on Oct 28
- #694 on Oct 29
- #695 on Oct 30
- #699 on Oct 31
Before you install
Network or broad shellAutomated signals, not a guarantee
Checked Nov 3, 2026
Not fully analyzed: some files were too long, unreadable or missing. This never lowers the level.
Show 10 notes
SKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzedSKILL.md:1Analysis incomplete: Referenced executable target unavailable; not analyzed
- No broad tool permissions
- No dangerous shell commands
- 167 network referencesin 8 files: scripts/fetch_news.py:65 user_sources.opml.example:22 scripts/fetch_bensbites.py:21 and 5 more
- No hidden or obfuscated text
- No instruction overrides
- 10 executable scriptsin 10 files: scripts/daily_briefing.py:1 scripts/debug_hf_detail.py:1 scripts/fetch_bensbites.py:1 and 7 more
- 1 reference to secretsin 1 file: .gitignore:52
- No requests to vote in Hot
Show all 178 signals by file
.gitignore
- Access to secretsline 52
[Credential-related source omitted]
README.md
- Network accessline 3
[](https://www.python.org/downloads/) - Network accessline 4
[](https://opensource.org/licenses/MIT) - Network accessline 5
[](https://github.com/cclank/news-aggregator-skill) - Network accessline 6
[](https://github.com/cclank/news-aggregator-skill/network) - Network accessline 88
npx skills add https://github.com/cclank/news-aggregator-skill - Network accessline 135
[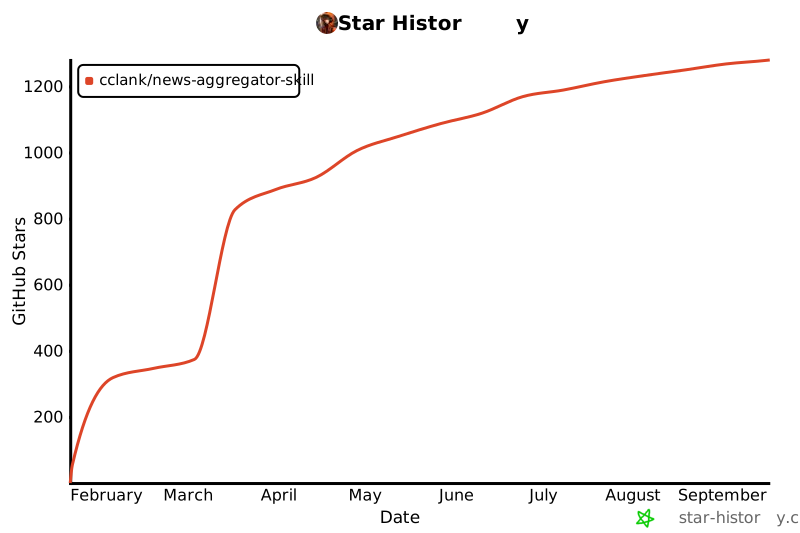](https://www.star-history.com/#cclank/news-aggregator-skill&Date)
SKILL.md
scripts/daily_briefing.py
- Executable scriptline 1
Executable file
scripts/debug_hf_detail.py
scripts/fetch_bensbites.py
- Executable scriptline 1
Executable file - Network accessline 21
url = "https://www.bensbites.com/" - Network accessline 25
api_url = "https://www.bensbites.com/api/v1/archive?sort=new&limit=12" - Network accessline 39
"source": "Ben's Bites", "title": post.get('title'), "url": f"https://www.bensbites.com/p/{post.get('slug')}", - Network accessline 40
"title": post.get('title'), "url": f"https://www.bensbites.com/p/{post.get('slug')}", "time": post.get('post_date', 'Recent').split('T')[0], - Network accessline 41
"url": f"https://www.bensbites.com/p/{post.get('slug')}", - Network accessline 55
href = link.get_attribute('href') if not href or "/p/" not in href: continue full_url = href if href.startswith("http") else f"https://www.bensbites.com{href}" - Network accessline 56
if not href or "/p/" not in href: continue full_url = href if href.startswith("http") else f"https://www.bensbites.com{href}" if full_url in seen_urls: continue - Network accessline 57
full_url = href if href.startswith("http") else f"https://www.bensbites.com{href}" - Network accessline 91
"source": "Ben's Bites", "title": "Ben's Bites (Visit Site)", "url": "https://bensbites.beehiiv.com/", - Network accessline 92
"title": "Ben's Bites (Visit Site)", "url": "https://bensbites.beehiiv.com/", "time": "Today", - Network accessline 93
"url": "https://bensbites.beehiiv.com/", "time": "Today", "summary": "Unable to fetch content. Please verify on site.",
scripts/fetch_generic_playwright.py
- Executable scriptline 1
Executable file
scripts/fetch_hf_papers_playwright.py
- Executable scriptline 1
Executable file - Network accessline 18
try: page.goto("https://huggingface.co/papers", timeout=60000, wait_until="domcontentloaded") - Network accessline 19
page.goto("https://huggingface.co/papers", timeout=60000, wait_until="domcontentloaded") - Network accessline 42
href = link_el.get_attribute("href") if href.startswith("/"): href = "https://huggingface.co" + href - Network accessline 44
href = "https://huggingface.co" + href
scripts/fetch_news.py
- Executable scriptline 1
Executable file - Network accessline 65
return "" try: response = requests.get(url, headers=HEADERS, timeout=5) - Network accessline 66
try: response = requests.get(url, headers=HEADERS, timeout=5) response.raise_for_status() - Network accessline 67
response = requests.get(url, headers=HEADERS, timeout=5) - Network accessline 113
api_url = f"http://hn.algolia.com/api/v1/search_by_date?tags=story&numericFilters=created_at_i>{timestamp_24h}&hitsPerPage={limit*2}&query={requests.utils.quote(query_str)}" - Network accessline 115
data = requests.get(api_url, timeout=10).json() - Network accessline 119
if not hits and raw_keywords: simple_query = raw_keywords[0] api_url_simple = f"http://hn.algolia.com/api/v1/search_by_date?tags=story&numericFilters=created_at_i>{timestamp_24h}&hitsPerPage={limit*2}&query={ - Network accessline 120
simple_query = raw_keywords[0] api_url_simple = f"http://hn.algolia.com/api/v1/search_by_date?tags=story&numericFilters=created_at_i>{timestamp_24h}&hitsPerPage={limit*2}&query={requests.utils.quote(simple_query)}" - Network accessline 121
api_url_simple = f"http://hn.algolia.com/api/v1/search_by_date?tags=story&numericFilters=created_at_i>{timestamp_24h}&hitsPerPage={limit*2}&query={requests.utils.quote(simple_query)}" - Network accessline 122
data = requests.get(api_url_simple, timeout=10).json() - Network accessline 128
"source": "Hacker News", "title": hit.get('title'), "url": hit.get('url') or f"https://news.ycombinator.com/item?id={hit['objectID']}", - Network accessline 129
"title": hit.get('title'), "url": hit.get('url') or f"https://news.ycombinator.com/item?id={hit['objectID']}", "hn_url": f"https://news.ycombinator.com/item?id={hit['objectID']}", - Network accessline 130
"url": hit.get('url') or f"https://news.ycombinator.com/item?id={hit['objectID']}", - Network accessline 131
"hn_url": f"https://news.ycombinator.com/item?id={hit['objectID']}", - Network accessline 148
base_url = "https://news.ycombinator.com" - Network accessline 154
url = f"{base_url}/news?p={page}" try: response = requests.get(url, headers=HEADERS, timeout=10) - Network accessline 155
try: response = requests.get(url, headers=HEADERS, timeout=10) if response.status_code != 200: break - Network accessline 156
response = requests.get(url, headers=HEADERS, timeout=10) - Network accessline 202
url = "https://weibo.com/ajax/side/hotSearch" - Network accessline 203
headers = { "User-Agent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/120.0.0.0 Safari/537.36", "Referer": "https://weibo.com/" - Network accessline 204
"User-Agent": "Mozilla/5.0 (Macintosh; Intel Mac OS X 10_15_7) AppleWebKit/537.36 (KHTML, like Gecko) Chrome/120.0.0.0 Safari/537.36", "Referer": "https://weibo.com/" } - Network accessline 205
"Referer": "https://weibo.com/" - Network accessline 208
try: response = requests.get(url, headers=headers, timeout=10) - Network accessline 209
response = requests.get(url, headers=headers, timeout=10) - Network accessline 222
# Construct URL (usually search query) # Web UI uses: https://s.weibo.com/weibo?q=%23TITLE%23&Refer=top - Network accessline 223
# Web UI uses: https://s.weibo.com/weibo?q=%23TITLE%23&Refer=top - Network accessline 224
full_url = f"https://s.weibo.com/weibo?q={requests.utils.quote(title)}&Refer=top" - Network accessline 241
query = f"{keyword.split(',')[0]} sort:updated" # Use first kw as primary url = f"https://github.com/search?q={requests.utils.quote(query)}&type=repositories" - Network accessline 242
url = f"https://github.com/search?q={requests.utils.quote(query)}&type=repositories" - Network accessline 243
# Note: GitHub Search page is hard to scrape due to login requirements (often). # Fallback strat: Topics? "https://github.com/topics/{kw}?o=desc&s=updated" - Network accessline 244
# Fallback strat: Topics? "https://github.com/topics/{kw}?o=desc&s=updated" - Network accessline 245
topic_url = f"https://github.com/topics/{keyword.split(',')[0].strip()}?o=desc&s=updated" try: response = requests.get(topic_url, headers=HEADERS, timeout=10) - Network accessline 246
try: response = requests.get(topic_url, headers=HEADERS, timeout=10) if response.status_code == 200: - Network accessline 247
response = requests.get(topic_url, headers=HEADERS, timeout=10) - Network accessline 256
repo_link = h3['href'] # /user/repo title = repo_link.strip('/') link = "https://github.com" + repo_link - Network accessline 258
link = "https://github.com" + repo_link - Network accessline 275
try: response = requests.get("https://github.com/trending", headers=HEADERS, timeout=10) - Network accessline 276
response = requests.get("https://github.com/trending", headers=HEADERS, timeout=10) - Network accessline 284
if not h2: continue title = h2.get_text(strip=True).replace('\n', '').replace(' ', '') link = "https://github.com" + h2['href'] - Network accessline 286
link = "https://github.com" + h2['href'] - Network accessline 306
def fetch_36kr(limit=5, keyword=None): try: response = requests.get("https://36kr.com/newsflashes", headers=HEADERS, timeout=10) - Network accessline 307
try: response = requests.get("https://36kr.com/newsflashes", headers=HEADERS, timeout=10) soup = BeautifulSoup(response.text, 'html.parser') - Network accessline 308
response = requests.get("https://36kr.com/newsflashes", headers=HEADERS, timeout=10) - Network accessline 318
"source": "36Kr", "title": title, "url": f"https://36kr.com{href}" if not href.startswith('http') else href, - Network accessline 319
"title": title, "url": f"https://36kr.com{href}" if not href.startswith('http') else href, "time": time_str, - Network accessline 320
"url": f"https://36kr.com{href}" if not href.startswith('http') else href, - Network accessline 330
data = requests.get("https://www.v2ex.com/api/topics/hot.json", headers=HEADERS, timeout=10).json() - Network accessline 348
def fetch_tencent(limit=5, keyword=None): try: url = "https://i.news.qq.com/web_backend/v2/getTagInfo?tagId=aEWqxLtdgmQ%3D" - Network accessline 349
try: url = "https://i.news.qq.com/web_backend/v2/getTagInfo?tagId=aEWqxLtdgmQ%3D" data = requests.get(url, headers={"Referer": "https://news.qq.com/"}, timeout=10).json() - Network accessline 350
url = "https://i.news.qq.com/web_backend/v2/getTagInfo?tagId=aEWqxLtdgmQ%3D" data = requests.get(url, headers={"Referer": "https://news.qq.com/"}, timeout=10).json() items = [] - Network accessline 351
data = requests.get(url, headers={"Referer": "https://news.qq.com/"}, timeout=10).json() - Network accessline 363
def fetch_wallstreetcn(limit=5, keyword=None): try: url = "https://api-one.wallstcn.com/apiv1/content/information-flow?channel=global-channel&accept=article&limit=30" - Network accessline 364
try: url = "https://api-one.wallstcn.com/apiv1/content/information-flow?channel=global-channel&accept=article&limit=30" data = requests.get(url, timeout=10).json() - Network accessline 365
url = "https://api-one.wallstcn.com/apiv1/content/information-flow?channel=global-channel&accept=article&limit=30" data = requests.get(url, timeout=10).json() items = [] - Network accessline 366
data = requests.get(url, timeout=10).json() - Network accessline 385
response = requests.get("https://www.producthunt.com/feed", headers=HEADERS, timeout=10) - Network accessline 429
# Increase timeout for detail fetch (10 pages * 5s = 50s + startup) - Network accessline 456
items = [] try: response = requests.get("https://www.latent.space/feed", headers=HEADERS, timeout=15) - Network accessline 457
try: response = requests.get("https://www.latent.space/feed", headers=HEADERS, timeout=15) response.raise_for_status() - Network accessline 458
response = requests.get("https://www.latent.space/feed", headers=HEADERS, timeout=15) - Network accessline 519
items = [] try: data = requests.get("https://lobste.rs/hottest.json", headers=HEADERS, timeout=10).json() - Network accessline 520
try: data = requests.get("https://lobste.rs/hottest.json", headers=HEADERS, timeout=10).json() for story in data: - Network accessline 521
data = requests.get("https://lobste.rs/hottest.json", headers=HEADERS, timeout=10).json() - Network accessline 540
items = [] try: url = "https://dev.to/api/articles?top=1&per_page=30" - Network accessline 541
try: url = "https://dev.to/api/articles?top=1&per_page=30" data = requests.get(url, headers=HEADERS, timeout=10).json() - Network accessline 542
url = "https://dev.to/api/articles?top=1&per_page=30" data = requests.get(url, headers=HEADERS, timeout=10).json() for art in data: - Network accessline 543
data = requests.get(url, headers=HEADERS, timeout=10).json() - Network accessline 563
return filter_items(fetch_rss_feed("https://sspai.com/feed", "少数派", limit * 2)[:limit], keyword) - Network accessline 575
cat_query = '+OR+'.join(f'cat:{c}' for c in cats) url = ( f"http://export.arxiv.org/api/query" - Network accessline 576
url = ( f"http://export.arxiv.org/api/query" f"?search_query={cat_query}" - Network accessline 577
f"http://export.arxiv.org/api/query" - Network accessline 584
for attempt in range(3): try: response = requests.get(url, headers=HEADERS, timeout=45) - Network accessline 585
try: response = requests.get(url, headers=HEADERS, timeout=45) response.encoding = response.apparent_encoding or 'utf-8' - Network accessline 586
response = requests.get(url, headers=HEADERS, timeout=45) - Network accessline 600
return filter_items(fetch_rss_feed("https://www.infoq.cn/feed.xml", "InfoQ 中文", limit * 2)[:limit], keyword) - Network accessline 606
raw = fetch_rss_feed("https://aihot.virxact.com/rss", "AIHOT", max(limit * 4, 50)) - Network accessline 614
raw = fetch_rss_feed("https://tldr.tech/api/rss/ai", "TLDR AI", limit * 4) - Network accessline 622
raw = fetch_rss_feed("https://importai.substack.com/feed", "Import AI", limit * 4) - Network accessline 627
INTERNATIONAL_NEWS_SOURCES = [ ("BBC Top News", "https://feeds.bbci.co.uk/news/rss.xml"), - Network accessline 628
("BBC Top News", "https://feeds.bbci.co.uk/news/rss.xml"), - Network accessline 629
("BBC World", "https://feeds.bbci.co.uk/news/world/rss.xml"), - Network accessline 630
("BBC Chinese", "https://feeds.bbci.co.uk/zhongwen/simp/rss.xml"), - Network accessline 631
("The Guardian World", "https://www.theguardian.com/world/rss"), - Network accessline 632
("Al Jazeera", "https://www.aljazeera.com/xml/rss/all.xml"), - Network accessline 633
("France 24", "http://www.france24.com/en/rss"), - Network accessline 636
REUTERS_GOOGLE_NEWS_RSS = ( "https://news.google.com/rss/search?" - Network accessline 637
"https://news.google.com/rss/search?" - Network accessline 730
("Ben's Bites", "https://www.bensbites.com/feed"), - Network accessline 731
("Interconnects", "https://www.interconnects.ai/feed"), # Fixed: needs www. - Network accessline 732
("One Useful Thing", "https://www.oneusefulthing.org/feed"), - Network accessline 734
("ChinAI", "https://chinai.substack.com/feed"), - Network accessline 735
("Memia", "https://memia.substack.com/feed"), - Network accessline 736
("AI to ROI", "https://ai2roi.substack.com/feed"), - Network accessline 737
("KDnuggets", "https://www.kdnuggets.com/feed"), - Network accessline 762
"source": "Ben's Bites", "title": "Ben's Bites (Visit Site)", "url": "https://bensbites.beehiiv.com/", - Network accessline 763
"title": "Ben's Bites (Visit Site)", "url": "https://bensbites.beehiiv.com/", "time": "Today", - Network accessline 764
"url": "https://bensbites.beehiiv.com/", "time": "Today", "summary": "Auto-fetch failed. Please verify on site.", - Network accessline 770
"source": "Ben's Bites", "title": "Ben's Bites (Check Site)", "url": "https://bensbites.beehiiv.com/", - Network accessline 771
"title": "Ben's Bites (Check Site)", "url": "https://bensbites.beehiiv.com/", "time": "Today", - Network accessline 772
"url": "https://bensbites.beehiiv.com/", "time": "Today", "summary": "Fetch process failed.", - Network accessline 791
PODCAST_SOURCES = [ ("Lex Fridman", "https://lexfridman.com/feed/podcast"), - Network accessline 792
("Lex Fridman", "https://lexfridman.com/feed/podcast"), - Network accessline 794
("80000 Hours", "https://feeds.transistor.fm/80-000-hours-podcast"), - Network accessline 795
("Latent Space", "https://latent.space/feed"), - Network accessline 798
ESSAY_SOURCES = [ ("Wait But Why", "https://waitbutwhy.com/feed"), - Network accessline 799
("Wait But Why", "https://waitbutwhy.com/feed"), - Network accessline 800
("James Clear", "https://jamesclear.com/feed"), - Network accessline 801
("Farnam Street", "https://fs.blog/feed"), - Network accessline 802
("Paul Graham", "http://www.aaronsw.com/2002/feeds/pgessays.rss"), - Network accessline 803
("Scott Young", "https://www.scotthyoung.com/blog/feed/"), - Network accessline 804
("Dan Koe", "https://thedankoe.com/feed/"), - Network accessline 879
'international': fetch_international, 'bbc_top': create_recent_rss_fetcher("https://feeds.bbci.co.uk/news/rss.xml", "BBC Top News"), - Network accessline 880
'bbc_top': create_recent_rss_fetcher("https://feeds.bbci.co.uk/news/rss.xml", "BBC Top News"), - Network accessline 881
'bbc_world': create_recent_rss_fetcher("https://feeds.bbci.co.uk/news/world/rss.xml", "BBC World"), - Network accessline 882
'bbc_chinese': create_recent_rss_fetcher("https://feeds.bbci.co.uk/zhongwen/simp/rss.xml", "BBC Chinese"), - Network accessline 883
'guardian_world': create_recent_rss_fetcher("https://www.theguardian.com/world/rss", "The Guardian World"), - Network accessline 884
'aljazeera': create_recent_rss_fetcher("https://www.aljazeera.com/xml/rss/all.xml", "Al Jazeera"), - Network accessline 885
'france24': create_recent_rss_fetcher("http://www.france24.com/en/rss", "France 24"), - Network accessline 954
# Secondary Fetch (Broad, no keyword)
scripts/fetch_user_feeds.py
- Executable scriptline 1
Executable file
scripts/process_general_json.py
- Executable scriptline 1
Executable file
scripts/rss_parser.py
- Executable scriptline 1
Executable file - Network accessline 106
for attempt in range(3): try: response = requests.get(url, headers=headers, timeout=15, verify=False) - Network accessline 107
try: response = requests.get(url, headers=headers, timeout=15, verify=False) response.raise_for_status() - Network accessline 108
response = requests.get(url, headers=headers, timeout=15, verify=False)
scripts/test_all_sources.py
- Executable scriptline 1
Executable file
user_sources.opml.example
- Network accessline 22
<!-- Simon Willison's Weblog (English, LLM and engineering) --> <outline type="rss" text="Simon Willison" title="Simon Willison" xmlUrl="https://simonwillison.net/atom/everything/" - Network accessline 23
<outline type="rss" text="Simon Willison" title="Simon Willison" xmlUrl="https://simonwillison.net/atom/everything/" htmlUrl="https://simonwillison.net/" /> - Network accessline 24
xmlUrl="https://simonwillison.net/atom/everything/" - Network accessline 25
htmlUrl="https://simonwillison.net/" /> - Network accessline 27
<!-- 阮一峰的网络日志 (Chinese tech weekly digest) --> <outline type="rss" text="阮一峰的网络日志" title="阮一峰的网络日志" xmlUrl="https://www.ruanyifeng.com/blog/atom.xml" - Network accessline 28
<outline type="rss" text="阮一峰的网络日志" title="阮一峰的网络日志" xmlUrl="https://www.ruanyifeng.com/blog/atom.xml" htmlUrl="https://www.ruanyifeng.com/blog/" /> - Network accessline 29
xmlUrl="https://www.ruanyifeng.com/blog/atom.xml" - Network accessline 30
htmlUrl="https://www.ruanyifeng.com/blog/" /> - Network accessline 37
BBC 中文 (already built in as --source bbc_chinese; keep as a custom-feed example only) <outline type="rss" text="BBC 中文" title="BBC 中文" xmlUrl="https://feeds.bbci.co.uk/zhongwen/simp/rss.xml" - Network accessline 38
<outline type="rss" text="BBC 中文" title="BBC 中文" xmlUrl="https://feeds.bbci.co.uk/zhongwen/simp/rss.xml" htmlUrl="https://www.bbc.com/zhongwen/simp" /> - Network accessline 39
xmlUrl="https://feeds.bbci.co.uk/zhongwen/simp/rss.xml" - Network accessline 40
htmlUrl="https://www.bbc.com/zhongwen/simp" /> - Network accessline 42
纽约时报中文网 (NYT Chinese) <outline type="rss" text="纽约时报中文网" title="纽约时报中文网" xmlUrl="https://cn.nytimes.com/rss.html" - Network accessline 43
<outline type="rss" text="纽约时报中文网" title="纽约时报中文网" xmlUrl="https://cn.nytimes.com/rss.html" htmlUrl="https://cn.nytimes.com/" /> - Network accessline 44
xmlUrl="https://cn.nytimes.com/rss.html" - Network accessline 45
htmlUrl="https://cn.nytimes.com/" /> - Network accessline 47
Hacker News Front Page (high-signal English tech) <outline type="rss" text="Hacker News Front Page" title="Hacker News Front Page" xmlUrl="https://hnrss.org/frontpage" - Network accessline 48
<outline type="rss" text="Hacker News Front Page" title="Hacker News Front Page" xmlUrl="https://hnrss.org/frontpage" htmlUrl="https://news.ycombinator.com/" /> - Network accessline 49
xmlUrl="https://hnrss.org/frontpage" - Network accessline 50
htmlUrl="https://news.ycombinator.com/" />
How the signals fit together
Facts from a static read of the files at the pinned commit. They describe what the code does, not why.
Some files could not be read; the facts below still hold.
Signal confidence: 1 fact
- Network access in code of documentationREADME.md:88Low confidence
Works with
| Agent | Status | Evidence | Install to |
|---|---|---|---|
| Claude Code | Compatible | Standard SKILL.md SKILL.md | .claude/skills/<skill-name>/ |
| Codex | Compatible | Standard SKILL.md SKILL.md | .agents/skills/<skill-name>/ |
| Cursor | Compatible | Standard SKILL.md SKILL.md | .cursor/skills/<skill-name>/ |
| Gemini CLI | Compatible | Standard SKILL.md SKILL.md | .gemini/skills/<skill-name>/ |
| GitHub Copilot | Compatible | Standard SKILL.md SKILL.md | .github/skills/<skill-name>/ |
| OpenCode | Compatible | Standard SKILL.md SKILL.md | .opencode/skills/<skill-name>/ |
- Native The repository ships a manifest, folder or frontmatter field for this agent.
- Compatible A standard SKILL.md that this agent can read.
- Unknown No evidence either way.
Derived automatically from paths, manifests and frontmatter. Not tested on each agent.
Explore alternatives and comparisons
Add this badge to your README
It updates every night and links to this page.
[](https://hotskills.dev/skill/cclank-news-aggregator-skill/)